The AI technology stack ▶ Watch
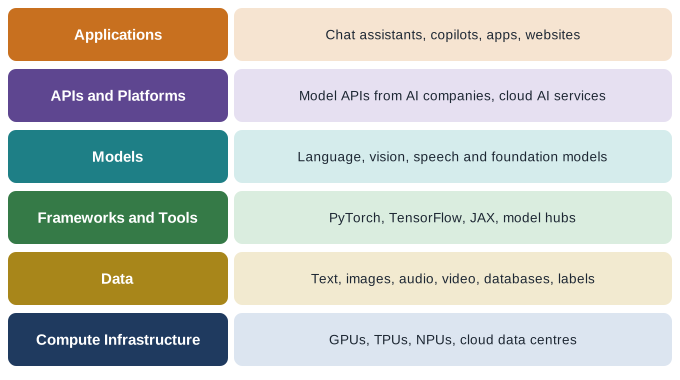
- Compute infrastructure - GPUs (graphics processing units), TPUs (Google's tensor processing units) and NPUs (neural processing units in phones and laptops), housed in huge cloud data centres.
- Data - collected, cleaned, labelled and stored datasets; for LLMs, trillions of words of text plus code, images and audio.
- Frameworks and tools - software libraries such as PyTorch, TensorFlow and JAX for building and training models, and model hubs for sharing them.
- Models - the trained networks. Large general models are called foundation models because many apps are built on top of them.
- APIs and platforms - AI companies and cloud providers offer models through an API (application programming interface), so developers can use them without training their own.
- Applications - the chat assistants, coding tools, smart features and agents people actually use.
Main neural network architectures ▶ Watch
| Architecture | Best at | Example uses |
|---|---|---|
| Feed-forward network | Simple patterns in numbers | Scoring, basic predictions |
| CNN (convolutional) | Images and video | Face unlock, medical scans |
| RNN / LSTM | Sequences, step by step | Older speech and translation systems |
| Transformer | Language and almost everything | LLMs, translation, vision, code |
| GAN (generative adversarial) | Realistic images | Image synthesis, style transfer |
| Diffusion model | High-quality image and video creation | Text-to-image, text-to-video |
| Autoencoder / VAE | Compressing and reconstructing | Denoising, anomaly detection |
| Mixture of Experts | Very large efficient models | Routing each input to specialist sub-networks |
The Transformer: the engine of modern AI ▶ Watch
Introduced in 2017 in a research paper titled "Attention Is All You Need", the Transformer replaced older step-by-step designs. Its key idea, self-attention, lets every word in a sentence look at every other word at the same time and decide which ones matter for understanding it.
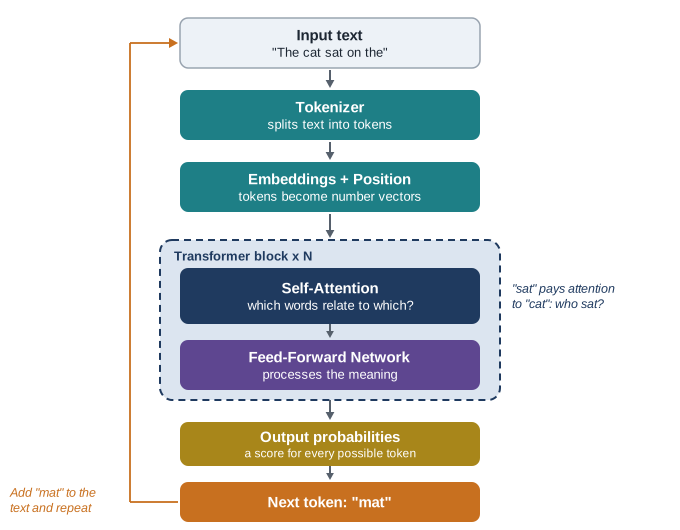
- Tokenizer - text is split into tokens (whole words or parts of words).
- Embeddings - each token becomes a list of numbers (a vector) representing its meaning, plus information about its position.
- Self-attention - each token gathers information from the other tokens it relates to. In "The cat sat on the mat because it was tired", attention helps link "it" to "cat".
- Feed-forward layers - process the combined information.
- Many blocks - attention and feed-forward blocks are stacked dozens of times; deeper blocks capture more abstract meaning.
- Output - the model produces a probability for every possible next token, picks one, adds it, and repeats.
Where the model runs ▶ Watch
- Cloud AI - the model runs in a data centre; your app sends a request over the internet. Most powerful, but needs a connection and costs per use.
- On-device (edge) AI - a smaller model runs on your phone or laptop. Fast, private and works offline, but less capable.
- Hybrid - simple tasks on the device, complex ones in the cloud. Many modern phones work this way.
Chapter summary
- An AI system is a stack: compute, data, frameworks, models, APIs and applications.
- Different architectures suit different data: CNNs for images, Transformers for language and more.
- Self-attention lets Transformers understand how all the words in a text relate to each other.
- Models can run in the cloud, on the device, or both.